• 7 min read
AWS’s 3 million-GPU plan also binds Trainium to Nvidia
AWS plans more than 3 million Nvidia GPUs through 2028, while coupling its Trainium roadmap to Nvidia networking and rack-scale interconnects.
Image: TechRadar
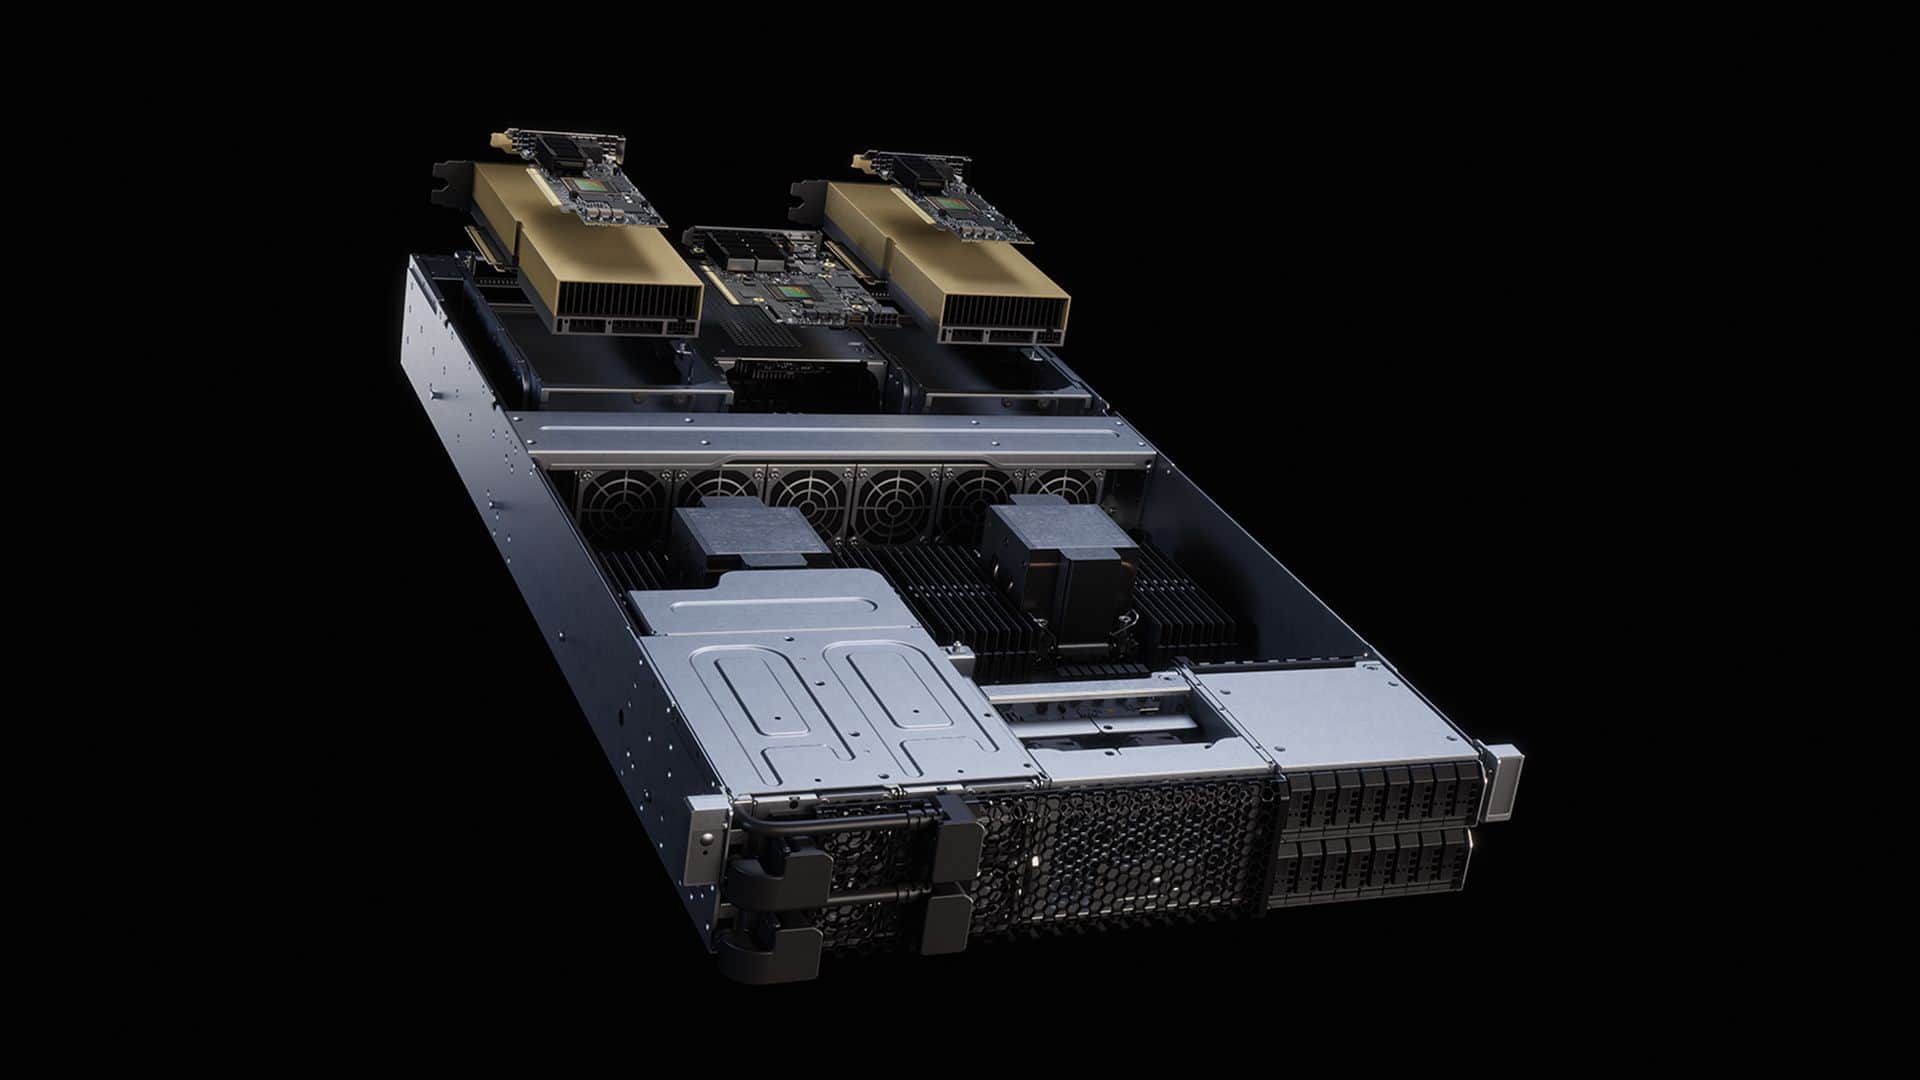
AWS plans to deploy more than 3 million Nvidia GPUs across its infrastructure through 2028. Amazon is also bringing Nvidia CPUs, networking, high-bandwidth memory work and NVLink Fusion into the infrastructure around its in-house Trainium chips.
The August 26, 2026 agreement adds 2 million Blackwell Ultra, Rubin and Rubin Ultra GPUs for AWS deployments in 2027 and 2028. It follows a March 2026 commitment for more than 1 million Nvidia GPUs beginning in 2026, bringing the combined planned total above 3 million. Nvidia said the earlier deliveries would run from 2026 through the end of 2027; AWS has not disclosed how many of those systems have been installed so far.
The scale is large enough that headline comparisons can become distorted. Amazon ended 2025 with about 1.58 million full- and part-time employees, meaning the announced Nvidia commitment is roughly 1.9 GPUs per employee. That ratio is not a useful measure of AWS staffing or capacity: most of Amazon’s workforce is in fulfillment and delivery, while the chips will sit in global cloud infrastructure.
Recommended reading
Euclyd has $231 million and Samsung, but no chip until 2028
Sergey Kuznetsov • • 4 min read
AWS finished Q2 2026 with $42.2 billion in revenue, up 37% year over year, and a $496 billion contracted backlog, compared with $364 billion three months earlier. Amazon says most AWS capacity being added for 2027 is already reserved, with customer reservations extending into 2028.
“Even at that amount, we will still not have enough capacity to meet all of the demand we have in 2026.”
Two Nvidia commitments, one incomplete deployment picture
The March and August agreements describe a pipeline rather than a count of GPUs already available to AWS customers. The newer deal names three Nvidia product generations but provides neither a per-generation allocation nor a regional rollout schedule. It also includes Nvidia CPUs, networking and interconnect technology, making it broader than a conventional GPU supply contract.
| AWS-Nvidia commitment | Announced | Planned quantity | Hardware and timing |
|---|---|---|---|
| First commitment | March 2026 | More than 1 million GPUs | Starting in 2026; Nvidia said deliveries run through end of 2027 |
| Additional commitment | August 26, 2026 | 2 million GPUs | Blackwell Ultra, Rubin and Rubin Ultra deployments in 2027 and 2028 |
There is also a definitional problem with the 2 million figure. Nvidia initially described its Vera Rubin rack as NVL144 at GTC 2025 by counting compute dies, then changed the presentation to Vera Rubin NVL72 before CES 2026 by counting 72 two-die packages. Rubin Ultra is expected to place four compute dies in a package.
AWS and Nvidia have not said whether their announced total refers to packages, individual compute dies, or another unit. That does not change the commercial commitment, but it limits direct comparisons with installed-GPU figures reported by other cloud providers or with the 196,000 Hopper GPUs Amazon was estimated to have bought in 2024.
About 100,000 GPUs in the new agreement are designated for secure AWS infrastructure supporting US federal and national-security workloads at Impact Level 6. The companies have not specified which GPU generation those systems will use, when they will come online, or whether that 100,000 is part of the 2 million total. The agreement describes it as part of the latest deployment plan, but does not publish a separate procurement schedule.
Trainium is becoming part of the Nvidia rack
AWS is not treating the Nvidia expansion as a replacement for its own accelerators. Trainium3 began shipping at the start of 2026, and Trainium4 is expected to begin deliveries in 2027. Amazon said in May that Trainium3 was nearly fully subscribed and that much of planned Trainium4 capacity had already been reserved; it also cited more than $225 billion in Trainium revenue commitments.
The change is in the interfaces. The earlier Nvidia agreement covered ConnectX and Spectrum-X networking. The August agreement adds work on Vera CPU-based infrastructure and expands NVLink Fusion support with Nvidia’s custom high-bandwidth memory technology. Nvidia and Amazon’s Annapurna Labs say the goal is future Trainium infrastructure in which Trainium accelerators and Nvidia GPUs can operate in a common rack-scale architecture.
Trainium remains Amazon’s alternative for AI training and inference. Amazon has said that using it at scale could save tens of billions of dollars in annual capital expenditure while providing several hundred basis points of operating-margin advantage over relying on other chips for inference. But a common rack design ties AWS custom silicon to Nvidia’s interconnect and memory ecosystem.
For customers, the promised benefit is the ability to deploy different accelerators inside a shared infrastructure design rather than treating Trainium clusters and Nvidia clusters as completely separate systems. Neither company has published the supported topology, bandwidth figures, software requirements, workload portability constraints, or a date for a Trainium4 system using NVLink Fusion.
The capital bill extends far beyond chips
Amazon raised its 2026 capital-expenditure forecast in July from about $200 billion to $220 billion, citing higher memory costs as a primary contributor. Cash capital expenditure reached $53.1 billion in Q2 2026, up from $31.4 billion a year earlier. For the first six months of 2026, it reached $96.3 billion, versus $55.6 billion in the same period of 2025.
| Period | Amazon cash capital expenditure | Comparison period |
|---|---|---|
| Q2 2026 | $53.1 billion | $31.4 billion in Q2 2025 |
| First half of 2026 | $96.3 billion | $55.6 billion in first half of 2025 |
Amazon says these outlays primarily cover technology infrastructure, much of it for AWS, plus fulfillment-network capacity. AWS typically commits to land, power, buildings, chips, servers and networking equipment six to 24 months before billing customers for the resulting capacity. Amazon can begin spending on a data center roughly two years before it opens; it puts the useful life of a data center above 30 years, against five to six years for chips, servers and networking gear.
The procurement schedule is a bet that AWS can align rapidly depreciating compute hardware with much slower construction of land, power and data-center facilities. Nvidia CFO Colette Kress has said the company remains supply-constrained, with memory and component costs also pressuring margins.
Power is another constraint. The International Energy Agency projects global data-center electricity consumption will rise from about 415 TWh in 2024 to roughly 945 TWh in 2030. Accelerated servers account for almost half of that projected increase, while cooling and other facility infrastructure account for another 20%. The agency estimates data centers can be operational in two to three years, but supporting energy infrastructure generally takes longer.
AWS is buying capacity ahead of silicon availability
The announcement follows the pattern documented on August 24, 2026, when GPU neoclouds were selling power before silicon: the binding constraint in AI infrastructure is often financing, electricity and a credible delivery path, not merely a reservation for accelerators. AWS has the balance sheet and contracted backlog to place orders years ahead; it also has a more immediate reason to do so, because it says available capacity will still trail demand.
Nvidia said specialist AI cloud providers CoreWeave and Nebius were expected to end 2026 with more than eight gigawatts of Nvidia GPU capacity, up from three gigawatts at the end of 2025. AWS is building its own Nvidia fleet while trying to preserve a cost and margin advantage through Trainium. The new architecture work makes those two approaches less separate than Amazon’s chip branding suggests.
The 3 million-plus number is still a commitment, not a verified installed base. AWS has not given a deployment-progress update for the March order, a cost for either agreement, instance pricing for the new hardware, or a breakdown of Blackwell Ultra, Rubin and Rubin Ultra allocations. Those omissions determine when customers can obtain capacity, on what infrastructure, and at what margin to AWS.
Frequently asked questions
When will AWS deploy the additional 2 million Nvidia GPUs?+
AWS plans deployments in 2027 and 2028. The chips will include Blackwell Ultra, Rubin and Rubin Ultra GPUs.
How many Nvidia GPUs has AWS committed to?+
AWS has committed to more than 3 million Nvidia GPUs across its March and August 2026 agreements. AWS has not disclosed progress on the earlier order.
Will AWS still use Trainium chips?+
Yes. Trainium3 began shipping at the start of 2026, and Trainium4 is expected in 2027. AWS is also planning common rack-scale infrastructure for Trainium and Nvidia GPUs.
How much is AWS spending on the Nvidia agreements?+
Neither AWS nor Nvidia has disclosed the cost of the GPU agreements. Amazon raised its overall 2026 capital-expenditure forecast to about $220 billion.

Editor-in-Chief
Sergey Kuznetsov is Head of Product at iXBT.com, one of the largest Russian-language technology media outlets, and the founder of itzine.ru. He has spent over a decade building and running tech newsrooms. At for(geeks) he sets editorial standards and reviews what ships.